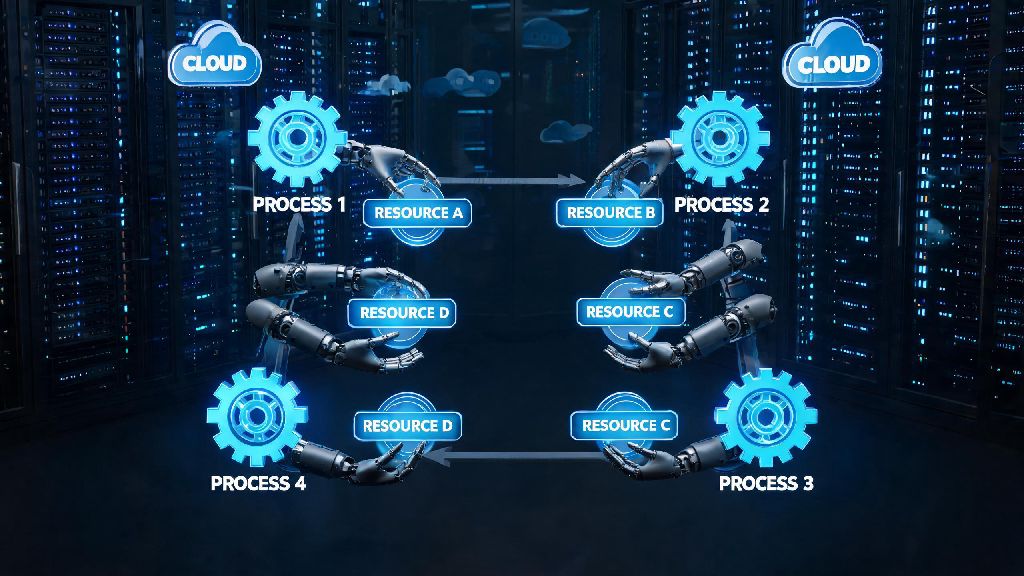
If you’ve ever had a frozen app, a database query that won’t load, or a server that stops responding for no obvious reason, you’ve probably run into a deadlock at some point. One of the most common questions new system admins, software engineers, and even CS students ask is what time period is deadlock set in, since the answer changes a lot depending on the environment you’re working with. There’s no one universal time frame, but breaking down how different systems handle resource allocation and conflict detection makes it easy to pin down for your use case. I’ve worked with both on-prem server stacks and cloud-native distributed systems for 8 years, so I’ll walk you through the most common scenarios, edge cases, and what you can do to speed up deadlock detection if you’re running into frequent issues.
What Time Period Is Deadlock Set In For Standard Operating Systems?
Operating systems handle deadlock detection at the kernel level, where they monitor all resource requests for CPU, memory, and I/O access across every running process. Most server-focused operating systems like Linux run deadlock detection checks every 1 to 10 milliseconds by default, to catch conflicts as early as possible without wasting excess system resources on constant scans. OS deadlocks for system processes are usually detected within 100ms of forming for most Linux server distributions, since those prioritize uptime over avoiding false detection.
User-facing operating systems like Windows and MacOS often use slightly longer detection windows, up to 30ms per scan, to avoid flagging temporary resource lags from high-load apps like video editors or games as deadlocks. That means deadlocks on personal devices may take 1 to 2 seconds to trigger a freeze or crash alert, which is a deliberate tradeoff to reduce annoying false warnings for regular users. You can adjust the kernel scan interval for most open-source operating systems, but lowering it below 1ms will usually lead to 10%+ higher CPU usage for detection scans alone.
Deadlock Time Frames For Relational and NoSQL Databases
Databases work very differently from core operating systems, because they handle thousands of concurrent queries competing for table, row, and page locks at any given time. Temporary wait times for locks are normal in high-volume databases, so deadlock detection windows are deliberately set longer to avoid flagging normal query lags as permanent deadlocks. Most default database deadlock detection windows fall between 1 and 5 seconds, with MySQL using a default 1 second interval, and PostgreSQL using 2 seconds by default.
Distributed databases like Cassandra and DynamoDB have even longer default detection windows, ranging from 10 to 30 seconds, because they have to cross-check lock status across multiple geographically separated nodes to confirm a deadlock is real, rather than just a temporary network lag between nodes. If you’re running an e-commerce site with frequent checkout queries, you might want to lower that interval to 500ms to reduce cart abandonment, but you’ll have to watch for false positives from slow cross-table joins on large product catalogs. Deadlocks are only considered fully “set in” once the detection window passes, so any resource wait shorter than that window is just treated as normal queue delay.
Key Factors That Shift Deadlock Detection Time Periods
When you’re calculating what time period is deadlock set in for your own stack, these three factors are the first things you should look at, since they can shift the standard window by 10x or more depending on your setup. I’ve seen teams waste weeks troubleshooting deadlock issues that were just caused by copying default settings from a small internal tool to a high-traffic customer platform, so these are worth checking first.
Even if two systems run the same software, their deadlock detection windows can be very different based on their business use case. For example, a internal company inventory tool can safely use a 10 second detection window with no negative impact, while a live event ticketing platform will need a 500ms window to avoid losing customers to frozen checkout pages.
How To Adjust Deadlock Time Periods For Your Use Case
If you’re running into frequent unresolvable deadlocks or too many false positive alerts, adjusting your deadlock detection time period is one of the easiest fixes you can make, no major code overhauls required. First, start by auditing your current deadlock logs to see how long most unresolved resource waits last before they clear on their own. Your detection window should be 20% longer than the average length of self-resolving temporary waits, to avoid flagging normal lags as deadlocks.
If you’re running a system where uptime is critical, like a healthcare patient record system, you can set a shorter window and pair it with a priority-based termination rule that only closes low-impact processes first, so you don’t risk disrupting critical services. For distributed systems, you can reduce detection time by using edge-based lock tracking that stores local lock status on each node, instead of waiting for a central controller to pull data from all nodes every cycle. Never set your deadlock detection window lower than 10ms for single-node systems, or 100ms for distributed systems, because you’ll end up wasting 10% or more of your CPU resources on constant lock checks, which will slow down all other processes.
At the end of the day, there’s no universal answer to what time period is deadlock set in, but you can narrow it down easily based on the system you’re working with and your business priorities. Most single-node operating systems detect deadlocks within 100ms, databases take 1 to 5 seconds, and distributed systems can take up to 30 seconds by default. Don’t be afraid to tweak your detection settings to match your needs, just make sure you test any changes in a staging environment first to avoid unexpected outages or excess resource use that harms performance for end users.