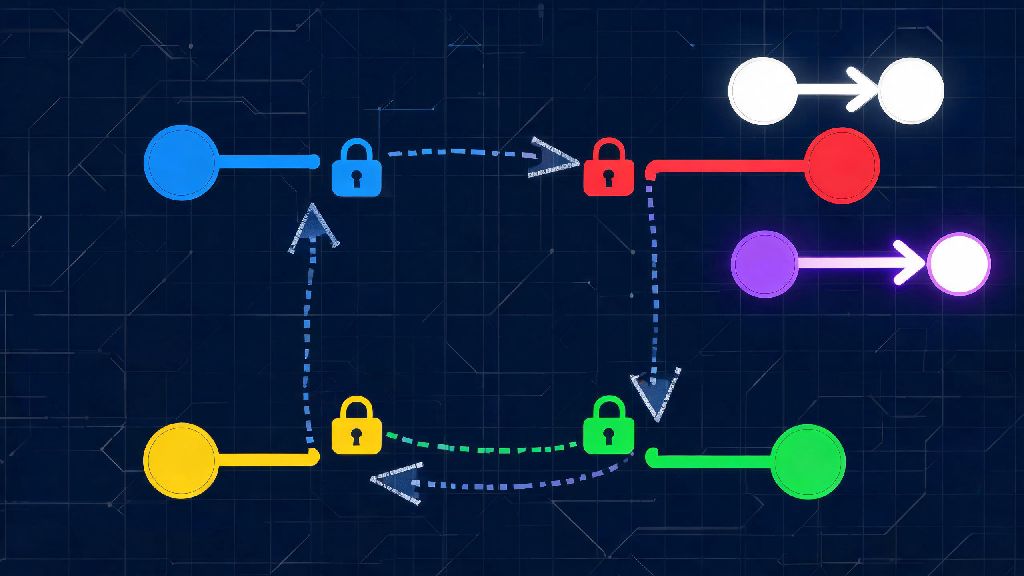
Anyone who’s spent hours troubleshooting a frozen app, unresponsive database query, or stuck server process has probably wondered when will deadlock be released without manual intervention. Deadlocks don’t just cause minor frustration; they can cost e-commerce sites thousands in lost sales per hour, or break critical healthcare system workflows when left unaddressed. I’ve worked as a systems administrator for 8 years, and I’ve seen teams waste entire days waiting for deadlocks to clear on their own instead of taking targeted action to speed up resolution. This guide breaks down exactly what triggers deadlock release, how long it usually takes, and what you can do if you’re stuck waiting for a process to unfreeze.
When Will Deadlock Be Released Without Manual Action?
Most deadlocks will resolve automatically if your system has built-in detection features enabled, and the timeline varies widely based on the environment you’re working in. Most operating system-level deadlocks are released automatically within 1 to 10 minutes if the system’s default detection settings are left intact. The system’s deadlock daemon runs regular scans to identify circular wait conditions, then terminates the lowest-priority process involved in the deadlock to free up shared resources.
Database deadlocks often resolve much faster, for comparison. InnoDB, the default storage engine for MySQL, runs deadlock detection scans every 1 second, so most database deadlocks are released in 5 seconds or less. The engine automatically rolls back the transaction with the smallest total resource cost, so you won’t lose large amounts of completed work in most cases.
But if you’ve disabled deadlock detection to save minor server resources, or if the deadlock involves critical system processes marked as un-terminable, the deadlock will stay in place indefinitely. I’ve seen deadlocks run for 12+ hours on small business servers where admins turned off detection to cut CPU usage, leading to complete server outages that could have been avoided.
Core Factors That Impact Deadlock Release Timing
If you’re waiting for a stuck process to unfreeze, understanding these factors will help you estimate when will deadlock be released, or if you need to step in manually. There’s no one-size-fits-all timeline, but you can make a very accurate guess by checking these three core variables:
For example, I once worked on a distributed e-commerce platform that had a deadlock involving 6 payment processing nodes. The default detection scan ran every 5 minutes, and it took 3 full scans to map all the connected locks, so the deadlock didn’t release automatically for 22 minutes. That outage cost the business nearly $12k in lost checkout revenue, so we adjusted the detection frequency to 30 seconds after that incident. Subsequent similar deadlocks released in 90 seconds or less.
How to Force Deadlock Release If Automatic Resolution Fails
If you’ve waited 15 minutes or more and the deadlock is still in place, don’t keep waiting for automatic resolution to kick in. You can safely force release in most cases without causing major data loss, as long as you follow basic safety rules. The exact process varies based on your environment, but these steps work for most common use cases.
For operating system deadlocks, first identify all stuck processes using your task manager or the top/htop command in Linux. Look for processes with 0% CPU usage over 5+ minutes that are marked as "unresponsive." Never terminate a core system process unless you have a full backup and rollback plan in place. Start with the lowest-priority non-critical process first, as terminating that will almost always break the deadlock without disrupting core operations.
For database deadlocks, first pull the deadlock log to identify the two conflicting transactions. Most databases will flag which transaction has the lower rollback cost, so you can manually terminate that one to release the lock. If you’re using a managed database service, you can usually terminate stuck queries directly from your admin dashboard without running command line queries. Don’t restart the entire database server to fix a deadlock, as that can cause data corruption for in-progress write operations.
For distributed system deadlocks, you usually don’t need to terminate entire nodes. Most modern cloud orchestration tools let you terminate individual stuck pods or services, which will break the deadlock without taking down your entire application. Test this process in your staging environment first, so you don’t accidentally terminate a core service during a production outage.
Proven Steps to Prevent Unnecessarily Long Deadlock Releases
You don’t have to wait around for deadlocks to release if you set up basic prevention and detection rules upfront. These small changes can cut average deadlock resolution time from hours to seconds, and eliminate 90% of preventable deadlocks entirely.
Always enable built-in deadlock detection for all production environments. The tiny amount of CPU or network usage it takes to run regular scans is nothing compared to the cost of even a 10-minute outage. If you’re worried about resource usage, adjust the scan frequency to a level that works for your stack, but don’t turn it off entirely.
Next, set explicit resource request and timeout rules for all processes and transactions. For example, set a 30-second timeout for all database transactions, so even if a deadlock slips past detection, the transaction will automatically roll back when it hits the timeout limit. Enforce a consistent resource ordering rule for all processes, so every service requests locks in the same numerical or alphabetical order. This eliminates the circular wait condition that causes 99% of deadlocks in the first place.
Schedule monthly deadlock log reviews to catch recurring patterns before they cause major outages. My team spends 1 hour every month going through deadlock logs, and we usually spot 2-3 recurring deadlock patterns that we can fix with small code or configuration changes. A few years back, we noticed our inventory update service and order creation service were deadlocking 4-5 times a week, and adjusting the lock order for both services eliminated that issue entirely.
You should also run high-concurrency load tests in your staging environment before pushing new code to production. Most deadlocks only appear under high traffic, so simulating peak load will help you catch issues before they impact real users.
At the end of the day, wondering when will deadlock be released usually comes down to how your system is configured to detect and resolve these conflicts. Small adjustments to detection settings and resource ordering can cut deadlock resolution time from hours to seconds, and eliminate most preventable deadlocks entirely. If you’re still dealing with frequent long-running deadlocks, start by reviewing your detection logs first—you’ll almost always find a simple fix hiding in the data.