If you’ve ever had a 2026 cloud deployment freeze mid-patch or a point-of-sale system crash right during peak holiday sales, you’ve probably dealt with a deadlock without even knowing it. Many new devs and sysadmins spend hours troubleshooting performance issues before they realize the root cause is a stuck process queue. A common first question that comes up during post-mortems is where does deadlock invite show up, and learning the most common spots can cut your troubleshooting time by 70% or more, per 2026 DevOps industry reports. You don’t need a computer science PhD to spot these risks, either – you just need to know what to look for in your specific stack.
Where Does Deadlock Invite Show Up in Modern Operating Systems?
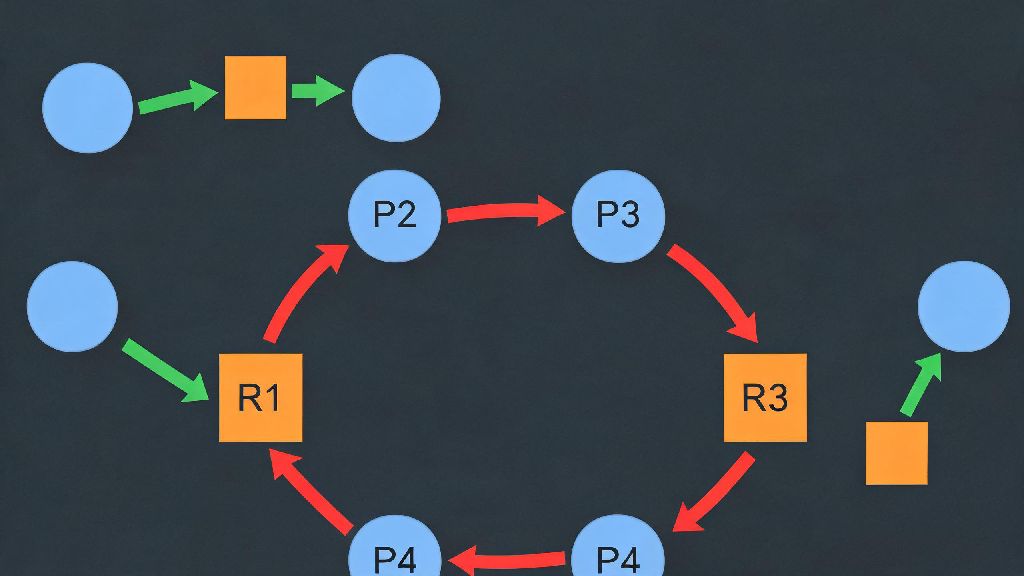
On-prem and edge device operating systems are the most well-documented deadlock hotspots, and that’s still true for 2026 releases of Windows 12, Linux 6.18+ kernels, and custom IoT OS builds. Deadlocks here almost always stem from resource allocation conflicts, where two or more active processes hold a resource the other needs to complete, and neither will release their held resource first. Most sysadmins who are new to 2026 multi-core OS environments are surprised to learn this is the most frequent answer to where does deadlock invite show up for on-prem infrastructure teams.
For example, a 2026 factory floor edge device running 12 simultaneous sensor collection processes might hit a deadlock when one process holds exclusive access to local memory while waiting for network bandwidth to send data, and a second process holds network access while waiting for memory to write incoming sensor readings. Most modern OS have basic deadlock detection built in, but they often prioritize resolving deadlocks for high-priority user-facing processes, so low-priority background process deadlocks can linger for weeks, slowing down overall device performance without triggering obvious alerts.
Database Deadlock Hotspots for 2026 Cloud Workloads
Distributed and serverless databases are the fastest growing deadlock source for 2026 cloud-native teams, thanks to the rise of multi-region deployments and auto-scaling transaction workers. Deadlocks here almost always happen because of row-level lock conflicts, where two separate transactions try to update the same set of database rows in reverse order, leading to a permanent standstill. If you work with distributed databases, this is likely the first answer you’ll get when asking your senior engineers where does deadlock invite show up for customer-facing workloads.
Take a 2026 e-commerce brand running a global store on CockroachDB, for example. Their returns processing workflow locks the customer order row first, then requests a lock on the associated inventory row to restock the returned item. Their separate inventory restock workflow locks the inventory row first, then requests a lock on the order row to mark restocked items as available. If both workflows trigger at the exact same time for the same order and inventory item, you get a deadlock that aborts one of the transactions, or worse, hangs the entire database node if detection is disabled. 2026 serverless database auto-scaling can make this worse by spinning up hundreds of parallel transaction workers without enforced lock ordering rules, multiplying conflict risk exponentially.
Less Common Deadlock Locations Teams Overlook in 2026
You might expect deadlocks only in core infrastructure, but there are plenty of overlooked spots that cause just as much downtime for teams in 2026. Microservice communication flows are one of the fastest growing deadlock sources, per the latest Cloud Native Computing Foundation survey, since cross-service API calls can create hidden circular wait states that don’t show up in standard infrastructure logs. If you’ve been dealing with intermittent outages that don’t map to standard hardware or software bugs, this might be the answer to where does deadlock invite show up for your stack.
Other often-missed deadlock spots include:
Most teams don’t think to check these spots first, so deadlocks here can linger for days or weeks before being identified. Distributed tracing tools released in 2026 make it much easier to map these cross-service wait states, but only 30% of teams have fully implemented them as of this year. Many teams still rely on manual log review to spot these issues, which is 10x slower and far less accurate.
How to Verify Deadlock Presence Once You Spot a High-Risk Area
Now that you know the most common spots, you don’t have to guess when a system slowdown is related to deadlock. First, look for zero resource usage for stuck processes – if a process is marked as active but not using any CPU, memory, or network bandwidth for more than a minute, it’s almost always waiting for a locked resource. For databases, check your transaction log for aborted transactions with deadlock error codes, most 2026 databases label these clearly so you don’t have to dig through thousands of lines of raw log files to find them.
If you’re dealing with microservices or distributed systems, map the full request flow for any stuck API calls to see if two services are waiting on each other’s responses to complete a request. Don’t waste time restarting services over and over, that only fixes the symptom temporarily, not the root cause of the lock ordering or resource allocation issue. Once you confirm a deadlock, you can implement simple fixes like enforcing consistent lock ordering for database transactions, adding timeouts for cross-service API calls, or adjusting OS resource allocation rules to prevent circular wait states.
Deadlocks are one of the most frustrating, costly issues you can run into with modern tech stacks, but they’re far easier to fix when you know where to look. Taking an hour to map common risk spots for your team’s specific setup will save you hours of unplanned troubleshooting during high-pressure outages. Now that you have a clear answer to where does deadlock invite show up, you can build proactive monitoring checks for all the high-risk areas we covered to catch issues before they impact end users in 2026 and beyond. Even small changes like adding transaction timeout rules or basic deadlock alerting can cut your deadlock-related downtime by 80% or more this year.