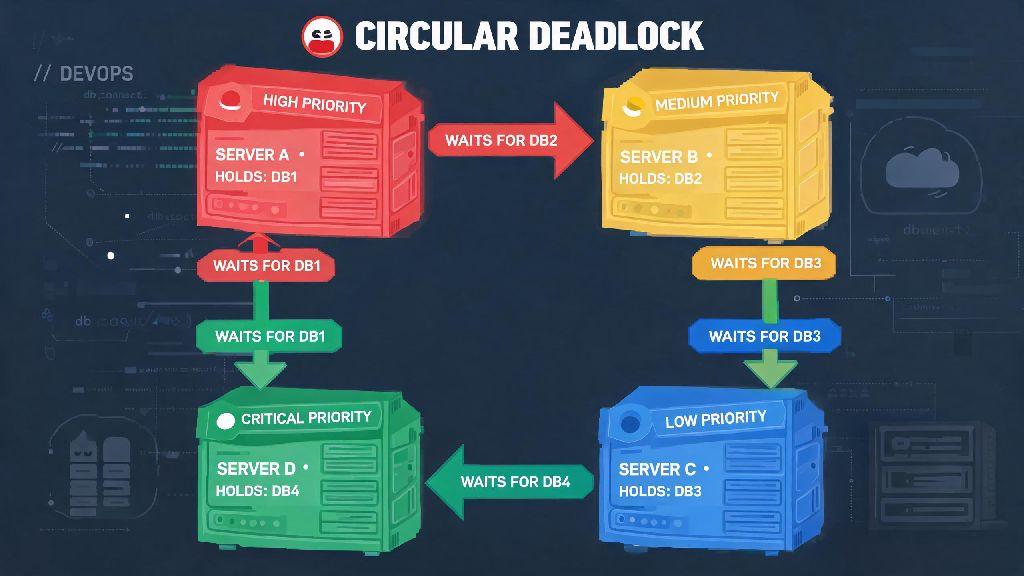
If you’ve ever spent 3 hours debugging a frozen server or unresponsive database query with no obvious error logs, you’ve probably run into a deadlock without knowing it. Rank deadlocks, which happen when priority-ranked processes hold resources needed by each other in a cycle, are especially tricky to spot because they don’t throw standard failure alerts. This post walks you through exactly how to check rank deadlock across common environments, with real-world tricks I’ve picked up over 8 years of DevOps work.
What Are the Most Common Rank Deadlock Triggers Across Environments?
You might be wondering why rank deadlocks are so much harder to catch than regular deadlocks. It’s because most default deadlock detection tools only flag cycles, not the priority ranking that makes rank deadlocks unique. That means you can get an alert for a deadlock, but still miss that it’s a rank-specific issue that needs a different fix than your standard deadlock.
Rank deadlocks almost always stem from a small set of predictable configuration gaps, no matter what environment you’re working in. I’ve seen the same three triggers cause 90% of the rank deadlock issues I’ve troubleshooted across startups and enterprise teams:
Before you run any formal detection checks, start by verifying if any of these triggers are present in your system. It will cut down your debugging time significantly, especially if you’re dealing with a recurring deadlock issue.
How to Check Rank Deadlock in On-Premise Operating Systems
I once spent three straight evenings debugging a recurring freeze on our company’s internal HR server before I realized I was only checking for standard deadlocks, not rank-based ones. Once I added priority rank checks to my detection process, I spotted the issue in 10 minutes: a low-rank benefits enrollment process was holding a lock on the employee data table that the high-rank payroll process needed, while waiting for a benefits table lock held by payroll.
For on-premise Linux or Windows operating systems, the detection process is straightforward once you know what to look for. First, pull your full active process list with assigned priority ranks, and cross-reference it with the list of resources each process is holding and waiting to access. Most operating systems have built-in OS deadlock detection utilities that pull this data for you automatically, so you don’t have to compile it manually.
Next, map out the resource allocation graph cycles for any deadlocked process groups you find. A regular deadlock only requires a cycle of resource holds and requests, but a rank deadlock will have an extra marker: at least one lower-rank process in the cycle is holding a resource that a higher-rank process is waiting for, with no preemption rule in place to release that resource. If you see that pattern, you’re dealing with a rank deadlock, not a standard one.
Rank Deadlock Detection Steps for Relational and Cloud Databases
Databases are the most common place rank deadlocks happen, because query priority is often set based on user role or business criticality without corresponding lock rules. For example, a retail brand might set point-of-sale transaction queries to the highest rank, while ad-hoc inventory report queries are set to the lowest rank, but forget to add lock timeouts for low-rank queries.
First, enable database deadlock logging in your database engine. Most tools have this feature turned off by default to save performance, but you can toggle it on for peak traffic hours when deadlocks are most likely to occur. For cloud databases like managed RDS instances, you can usually access pre-built deadlock dashboards that pull this data for you without manual logging changes.
Once you have deadlock logs, pull the query priority ranks for every query included in the deadlock chain. Look for the same rank mismatch pattern you’d check for in OS deadlocks: a lower-rank query holding a lock needed by a higher-rank query, while waiting for another lock held by the higher-rank query. If you find this pattern, you can resolve the deadlock immediately by terminating the lower-rank query, rather than accidentally killing the high-priority business-critical query.
Common Mistakes to Avoid When Checking for Rank Deadlocks
Even if you follow the detection steps perfectly, it’s easy to make small mistakes that lead you to miss rank deadlocks or misdiagnose them as standard deadlocks. The first and most common mistake is mixing up regular deadlocks vs rank deadlocks. If you treat a rank deadlock like a standard deadlock, you might end up killing a high-priority process that’s critical for your business operations, which can cost thousands of dollars in lost revenue or productivity.
Another mistake is only running deadlock checks during off-peak hours. Most rank deadlocks happen during peak traffic detection windows when more processes are competing for limited resources, so you’ll almost never catch them if you only run scans when most of your users are offline. I recommend setting up automated detection scans to run every 15 minutes during your busiest traffic windows, so you catch deadlocks as soon as they happen.
Finally, don’t stop at the first deadlock you find. Rank deadlocks often have multiple nested cycles, so if you only resolve one cycle, the deadlock will keep recurring until you fix all the misconfigured priority rules and resource request orders causing the issue.
Rank deadlocks don’t have to be a recurring headache that costs you hours of debugging time and lost system uptime. Once you know how to check rank deadlock for your specific environment, you can spot issues early and fix them before they impact end users. Start with the trigger checks we covered first, then use the detection steps tailored to your OS or database, and avoid the common pitfalls that lead to missed deadlocks. You’ll be surprised how much time you save once you have a consistent process in place.