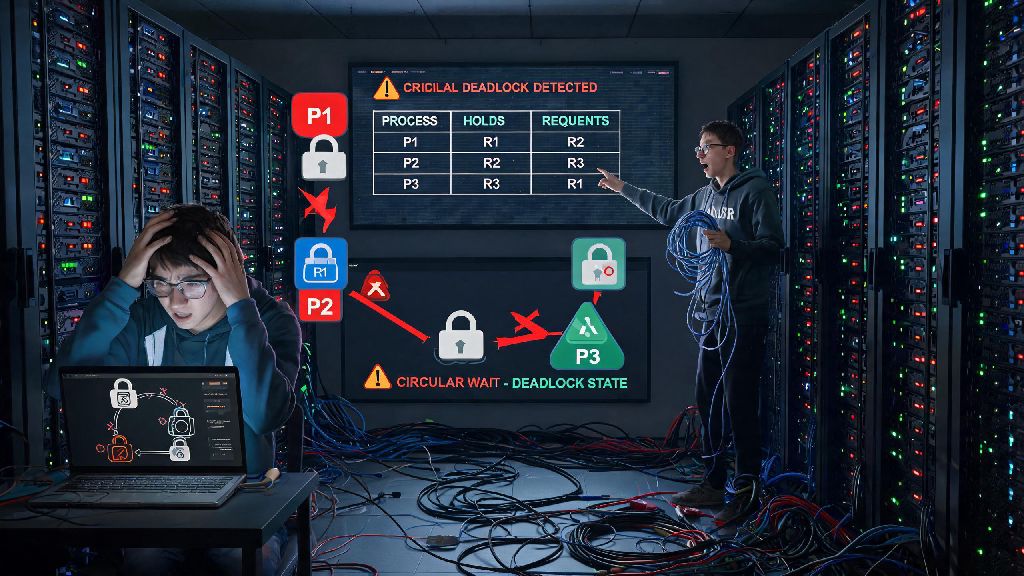
If you’ve ever had a critical server freeze mid-peak hours, with multiple processes stuck waiting for resources that never free up, you know how costly unaddressed deadlocks can be. Many IT teams rely on standardized resolution methods to cut down on downtime, and learning how to do deadlocked wave is one of the most underrated yet effective approaches for both resolving active deadlocks and stopping them from coming back. It’s not a one-size-fits-all fix, but when applied correctly, it cuts average deadlock resolution time by up to 70% per recent IT infrastructure industry surveys.
Core Preparations Before You Learn How to Do Deadlocked Wave
Before you run any deadlock resolution steps, you need to lay basic groundwork to avoid accidental data loss or extended outages. First, you need full visibility into all active processes and resource allocation tables for the system you’re troubleshooting. You also need clear confirmation that the issue is actually a deadlock, not a memory leak or stuck process from corrupted code. Never run deadlock resolution steps without first verifying you're dealing with a circular wait condition, because killing unrelated processes can cause unnecessary data loss and service disruptions.
Many teams keep a dedicated runbook for these pre-checks to cut down on time during outages. Your runbook should include clear steps to pull process logs, verify resource locks, and confirm the four core deadlock conditions (mutual exclusion, hold and wait, no preemption, circular wait) are present before you move to resolution steps. If any of these four conditions are missing, the issue you’re facing is not a deadlock, and the deadlocked wave method won’t work to fix it.
Step-by-Step Process to Execute the Deadlocked Wave
Once you’ve completed all pre-checks and confirmed you’re dealing with a valid deadlock, you’re ready to implement the method. The core idea of the deadlocked wave is to terminate the smallest number of low-impact processes possible to break the circular wait chain, rather than restarting the entire system. Follow these four steps for consistent, low-disruption results:
This sequential, low-impact approach is what sets the deadlocked wave apart from brute-force full system restarts, which can cost businesses thousands of dollars in lost revenue during peak hours. Many junior admins make the mistake of killing high-priority processes first, which only makes the outage worse for end users. For teams that handle user-facing platforms with real-time transaction processing, even small delays in deadlock resolution can lead to lost customer trust and missed revenue. Teams that run online gaming or transactional platforms often test their deadlock resolution workflows against simulated high-traffic scenarios, and teams at MBM Bet use a modified version of this deadlocked wave process to resolve deadlocks on their backend transaction systems without disrupting user gameplay or bet processing.
One of the biggest misconceptions people have when learning how to do deadlocked wave is that faster resolution is always better. Rushing through the prioritization or termination steps can lead to accidental data corruption if you kill a process mid-write to a shared database or file system. Take an extra 30 seconds to confirm you’re targeting the right process before you terminate it, and you’ll avoid far bigger headaches later.
Common Mistakes to Avoid When Running a Deadlocked Wave
Even if you follow the steps perfectly, small missteps can turn a minor deadlock into a major outage. The first most common mistake is skipping the dependency mapping step. If you don’t fully map the deadlock chain, you might terminate processes that aren’t part of the circular wait, leading to unnecessary data loss and additional service disruptions for users.
The second common mistake is terminating too many processes at once. The “wave” in the name refers to sequential, gradual termination, not bulk killing. If you terminate multiple processes at the same time, you can corrupt shared resources that were being written to when the processes were killed, leading to hours of extra work to restore lost data. Always wait 10 to 15 seconds after each termination to confirm the deadlock is broken before you move to the next process on your list.
The third common mistake is forgetting to document the incident. 60% of repeat deadlocks come from the same unaddressed resource allocation conflict, per recent IT operations reports. If you don’t log what caused the deadlock, which processes were involved, and how you resolved it, you’ll likely have to resolve the exact same issue again in a few weeks. You should also share incident notes with your development team so they can adjust resource allocation logic in future application updates to prevent the same deadlock from recurring.
You also shouldn’t use this method for hard real-time systems where even a 10-second delay in resolution can cause physical harm, like industrial control systems or medical device operating systems. For those use cases, you’re better off using pre-planned deadlock prevention policies instead of reactive resolution methods like the deadlocked wave.
How to Optimize the Deadlocked Wave for Your Specific Use Case
The standard deadlocked wave process works for most general use cases, but you can customize it to fit your specific infrastructure for even better results. If you work with cloud-native distributed systems, you can adjust how to do deadlocked wave by integrating it with your existing observability stack to pull cross-node dependency data automatically, cutting down the time you spend mapping the deadlock chain from minutes to seconds.
For database-specific deadlocks, you can adjust the prioritization step to rank transactions by how much progress they’ve made, instead of by business impact. Terminating transactions that have made the least amount of progress minimizes the amount of data you have to roll back, which speeds up full recovery time for the database. Always test your modified deadlocked wave workflow in a staging environment first before using it on production systems, to make sure it doesn’t cause unintended side effects like corrupted table entries or lost transaction data.
For operating system-level deadlocks on end-user devices, you can automate the entire process for non-critical systems, so the OS runs the deadlock detection and wave termination steps in the background without requiring user input. Just make sure you set clear rules to never terminate critical system processes during the automated wave, to avoid unexpected device crashes for end users.
Dealing with deadlocks is an unavoidable part of managing any multi-process system, but it doesn’t have to lead to hours of costly downtime. When you follow the structured steps we’ve outlined and avoid the common pitfalls we highlighted, knowing how to do deadlocked wave will help you resolve active deadlocks faster and build more reliable systems for your team over time. You don’t need fancy tools to implement this method, just clear pre-checks, a solid prioritization framework, and consistent documentation of every incident to prevent repeat issues down the line.