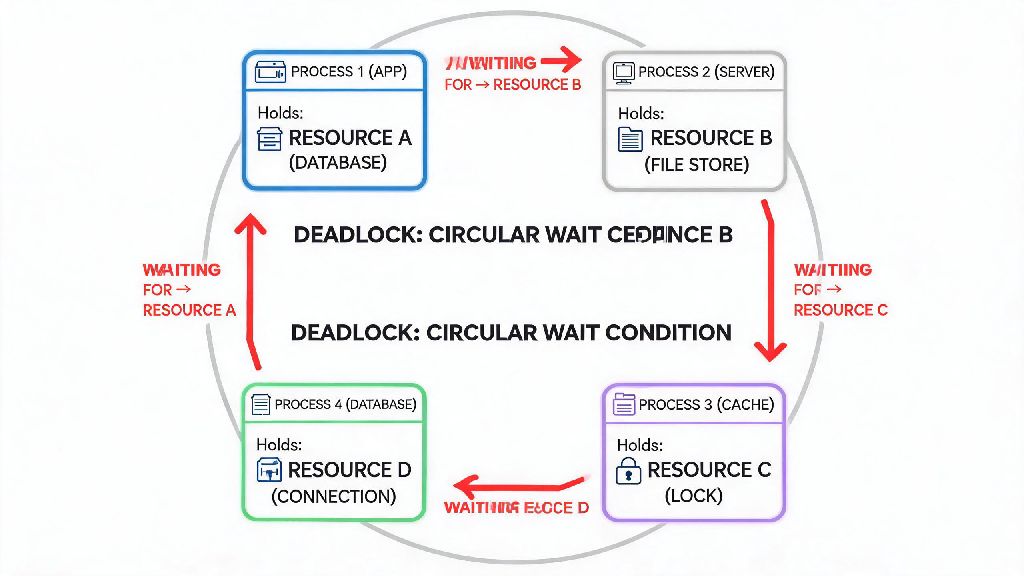
If you’ve ever had a point-of-sale system freeze mid-transaction during a holiday rush, or a cloud app stop responding while processing hundreds of user orders, you’ve likely encountered a deadlock. These events are notoriously frustrating to fix, even for seasoned tech teams. If you’re new to backend development or system administration, you’ve probably asked what difficulty is deadlocked systems actually present, and why they’re so hard to mitigate before they cause widespread disruption. This guide breaks down those challenges, real-world risks, and practical steps you can take to address and prevent deadlocks on your systems.
What Difficulty Is Deadlocked Systems Present for Day-to-Day Operations?
Deadlocks don’t just cause minor slowdowns — they can bring critical business processes to a complete halt, with effects that ripple across every part of your operation. Most teams don’t realize how severe these impacts can be until they face a deadlock during peak traffic, because these issues rarely show up in low-volume staging environments. The most immediate challenges include:
I once worked with a small retail brand that spent 3 hours troubleshooting a frozen checkout system during Black Friday, only to find the issue was a deadlock between two inventory update processes that no one had flagged in testing. Most new developers underestimate what difficulty is deadlocked scenarios can cause, because they only learn about deadlocks as a theoretical concept in computer science classes, not as a real-world problem that can shut down entire businesses. Even small teams with limited engineering resources can face tens of thousands of dollars in losses from a single deadlock event if they’re not prepared.
Common Root Causes Behind Deadlocked Systems
If you’re still learning what difficulty is deadlocked processes can create, understanding the four core conditions that make deadlocks possible will help you spot potential risks before they turn into outages. These conditions, called the Coffman Conditions, all need to be present at the same time for a deadlock to occur. First, mutual exclusion, where only one process can access a shared resource (like a database table or server memory slot) at a time. Second, hold and wait, where a process holds one resource while waiting for access to another that’s held by a different process. Third, no preemption, meaning the system can’t force a process to release a resource it’s already holding, even if that process is idle. Finally, circular wait, where each process in a chain is waiting for a resource held by the next process in the line.
Most deadlocks don’t happen because of a single bad line of code, but because of unforeseen interactions between separate features added over time. For example, a developer might add a new discount calculation feature that accesses the customer table first before pulling order data, while the existing checkout flow accesses the order table first before pulling customer data. This creates a circular wait that only triggers when both processes run at exactly the same time, which might not happen during standard low-volume testing. So you could have a feature running for weeks without issues, only to cause a deadlock the first time you run a site-wide sale that drives 10x your normal traffic.
How to Diagnose Deadlocked Systems Fast
When your system freezes up and you suspect a deadlock, the first priority is to confirm the issue and resolve it as fast as possible, without making the problem worse. For operating systems, use built-in monitoring tools to check for processes that have been in a waiting state for more than 30 seconds with no CPU or memory usage changes. These processes are almost always stuck waiting for a resource that’s being held by another process. For databases, most modern SQL platforms have built-in deadlock logs that show you exactly which transactions are stuck, what resources they’re holding, and what resources they’re waiting for, so you don’t have to guess.
Don’t make the common mistake of killing random processes to unfreeze the system, because you might accidentally terminate a critical customer-facing process that leads to permanent data loss. Instead, prioritize killing the process that has the least unsaved work, or the one that has been running for the shortest amount of time if you don’t have clear logs. Once you’ve dealt with a few of these events firsthand, you’ll have a much clearer sense of what difficulty is deadlocked systems present, and why proactive monitoring is worth the extra setup time.
In many cases, you can set up automated alerts to notify your team as soon as a potential deadlock is detected, so you can address it before it causes widespread outages. Just make sure you tune these alerts properly to avoid false positives that pull your team away from other important work. A good rule of thumb is to only trigger an alert if two or more processes have been in a waiting state for more than a minute, with no signs of progressing.
Long-Term Fixes to Reduce Deadlock Risk
You don’t have to completely rewrite your system to cut down on deadlock events. Small, targeted changes to your development and monitoring workflows can reduce your deadlock risk by 80% or more, based on industry data. First, adjust your resource access order: make sure all processes across your system access shared resources in the same sequence, so you eliminate the circular wait condition entirely. For example, if every process that needs access to both the customer and order tables pulls customer data first, you’ll never have the conflicting access order that causes most database deadlocks.
Second, set timeouts for all resource requests, so if a process can’t get the resource it needs within a set window, it releases all the resources it’s holding and tries again later. This breaks the hold and wait condition, so processes can’t hang onto resources indefinitely while waiting for others. Third, avoid holding locks for longer than necessary: don’t keep a database lock open while you run non-critical calculations that don’t need access to that resource. The less time processes hold onto shared resources, the lower the chance that two processes will try to access the same resources at the same time.
So if you’re building a new feature that interacts with shared system resources, test it under high-traffic load before launching it to production. Many teams skip load testing for small feature updates, but that’s exactly how unforeseen deadlocks slip through to live users. You don’t need fancy enterprise testing tools either: even a simple open-source load testing tool can simulate 10x your normal traffic to spot potential deadlock risks before they impact your customers.
If you’ve ever spent hours troubleshooting a frozen system with no obvious error, you already have a sense of what difficulty is deadlocked processes can cause for teams of all sizes. You don’t need to be a senior systems engineer to reduce your risk, either: implementing basic access order rules, setting up deadlock logging, and testing new features under load can eliminate the vast majority of deadlock events before they cause costly outages. Don’t wait for a disruptive issue during your busiest season to start addressing deadlock risk: even a few hours of setup work now can save you days of stress and lost revenue later.